Architecture
PDQ combines advanced automation with end-to-end active metadata management. It is the foundation for data operations that are efficient, transparent and fully automated.
By integrating PDQ into your infrastructure you ensure that modelling, quality, versioning, integration, code generation and orchestration hold together as one unit — not as a collection of loosely coupled tools.
From source to delivered value
Ingest, Data Lake Service and Data Warehouse Automation in one coherent flow — with catalogue, monitoring, orchestration, automation, observability and traceability across the whole chain.
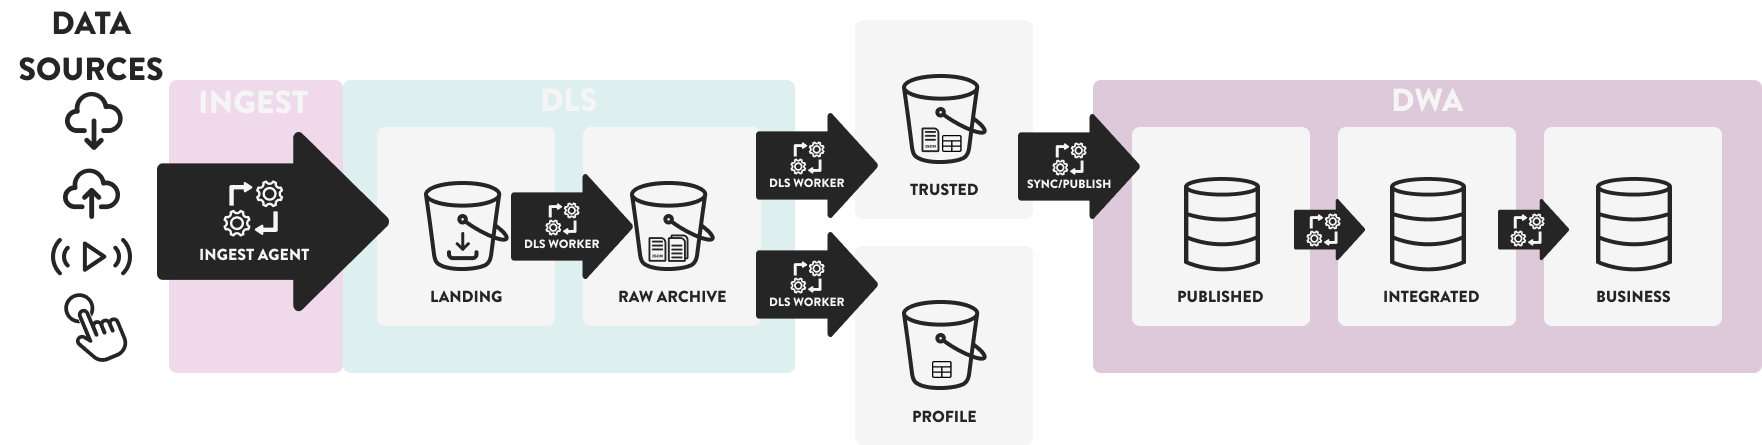
PDQ's reference architecture. Every step is driven by active metadata, which makes the flow traceable from data source to delivered report.
The same flow is rendered live on the PDQ dashboard, drawn from the systems, source files and models actually configured in your installation. Solid lines are deliveries that go via the Ingest Agent, dashed lines are direct transfers, and the icon on each source shows whether it is a database, an API, a file source, a custom connector or a manual delivery.
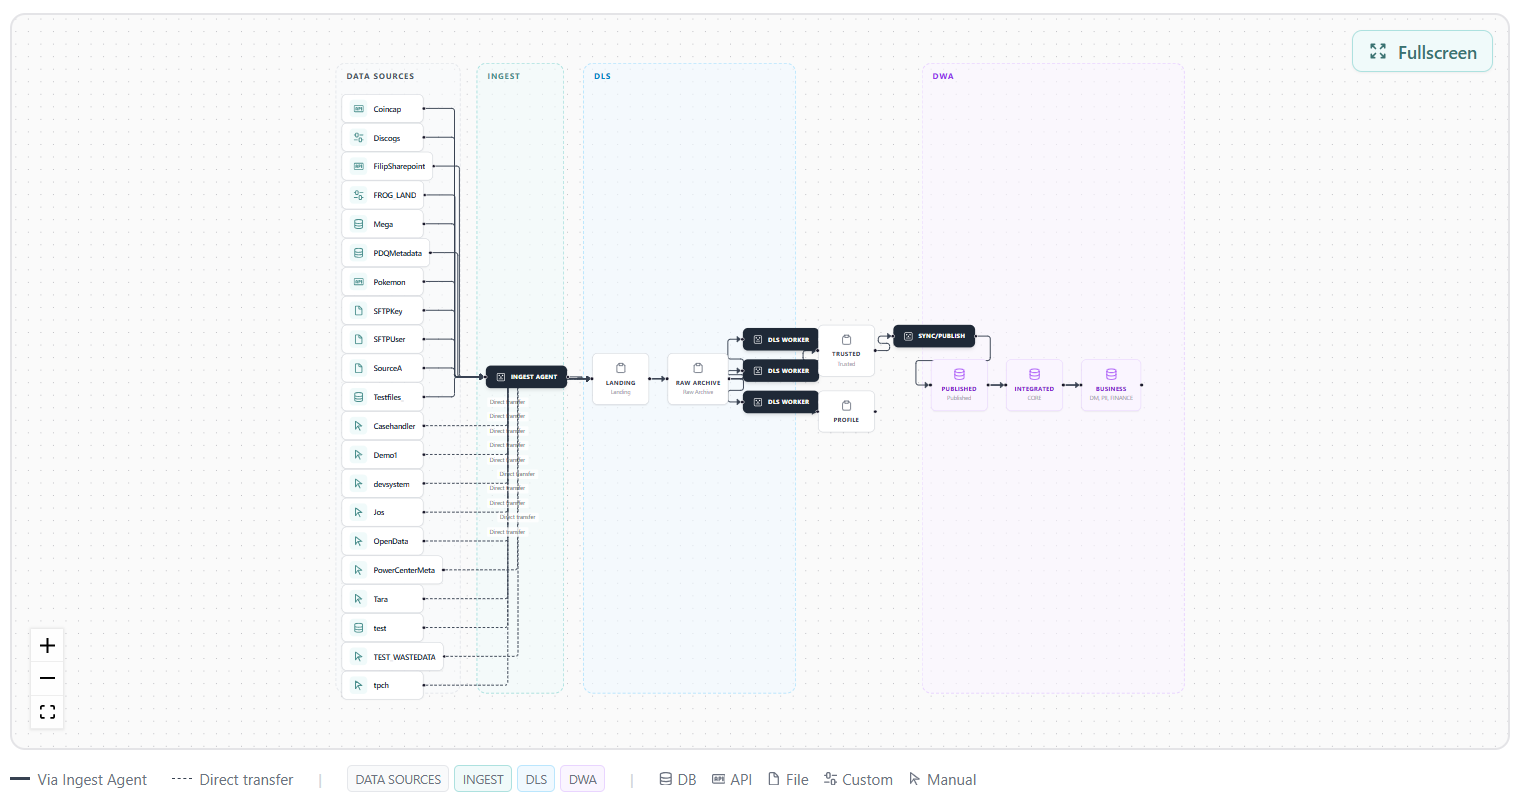
Every stage owns one responsibility. That is what makes a fault locatable, and a layer replaceable without rewriting the rest. Metadata drives the run: lineage, versions and compliance fall out of the flow rather than being separate projects.
The stages in detail
Sources — Data sources
What Files, APIs, streams and databases — the source systems as they actually are, with no preparation.
Why Sources change without asking. The platform has to absorb that without anyone rewriting a pipeline.
How Each source is described as metadata: connection, schema and load window. A new source is a configuration, not a project.
Ingest — Ingest Agent
What The agent pulls data and lands it unchanged.
Why What arrived has to stay separable from what we did to it, or no reconciliation is possible after the fact.
How The agent runs close to the source, writes files untouched, and stamps every delivery with its time and origin.
DLS — Data Lake Service
What Landing → Raw Archive → Trusted, with Profile alongside.
Why Raw data is preserved unchanged while quality assurance happens on the way to Trusted. Two different jobs, two different layers.
How Profiling and quality rules run as part of the flow. Only hard failures such as missing business key and completely wrong structure fails and never reaches Published, the rest is processed since we cannot stop all use cases at this point. The deviation will be recorded for audit.
DWA — Warehouse Automation
What Published → Integrated → Business. From quality-assured source data to an integrated, historised model and finally a business-facing delivery layer.
Why Integrated is the core: a normalised, historised model where every value carries a validity period. That is what makes "what did we know then?" answerable.
How The model is the source. Load logic, historisation and point-in-time views are generated from it — nobody writes historisation logic by hand.
Delivery — Out to the business
What Reports and BI, APIs, AI and ML workflows, and direct SQL access.
Why Every consumer reads the same quality-assured base. One number — not one number per tool.
How The business layer exposes business-facing views over the normalised model. The complexity sits next to the model, not next to the user.
Active metadata — Capabilities around the whole chain
What Data catalogue, monitoring, orchestration, automation, observability and traceability.
Why They wrap the whole chain instead of living in six separate tools. The metadata does not just describe the system — it runs it.
How Active metadata drives every step, so lineage, versions and compliance fall out of the run rather than being documented beside it.
Technology-agnostic by design
The platform sits on top of your stack — not the other way around.
Change the database, change the storage, change the cloud. The model, the logic and the metadata come with you. That is what turns vendor leverage from a talking point into a fact.
The layers are independent of each other: changing database or storage is a configuration change, changing cloud a migration.
| Layer | Supported options |
|---|---|
| Any database | Snowflake, Databricks, SQL Server, Synapse, Fabric, PostgreSQL |
| Any storage | Azure Blob, Amazon S3, CEPH, Swift, MinIO |
| Any cloud | Azure, AWS, Cleura |
What the platform actually does
Modelling and code generation
The data model is the source. Load logic, historisation and structures are generated from it — consistent no matter who builds it, and without hand-written ETL that drifts apart over time.
Governance in the target, not beside it
The same generation run that builds the tables also documents and classifies them. Column and table comments, primary keys, foreign keys, unique constraints, category tags and sensitivity tags are emitted from the declarations already made in the data contract and the model — so a classification set once on a source field arrives on the target column, including on the normalised child tables that inherit the key.
→ What lands in the target environment
Quality and profiling
Profiling and quality rules run as part of the flow, not as an afterthought. Anomalies are caught where they occur and stop what needs stopping.
Orchestration and operations
Dependencies, run order, re-runs and alerting are handled centrally. Production-ready from day one instead of months of scaffolding.
Active metadata
The metadata does not just describe the system — it runs it. Lineage, versions and compliance are by-products of execution, not separate projects. It is also portable: the REST API serves the whole repository, and every execution emits OpenLineage events, so lineage reaches the catalogue you already run rather than staying inside the console.
DLS and DWA — what happens where
| Stage | Layer | What happens |
|---|---|---|
| Ingest | Into the platform | The ingest agent pulls data from files, APIs, Message Queues and databases and lands it in Landing without altering it. |
| DLS | Data Lake Service | Landing → Raw Archive → Trusted, with Profile alongside. Raw data is preserved unchanged; Conformity happens on the way to Trusted. |
| DWA | Data Warehouse Automation | Published → Integrated → Business. From quality-assured source data to an integrated, historised model and finally a business-facing delivery layer. |
| Delivery | Out to the business | Reports, APIs, dashboards, AI and ML workflows and direct SQL access — all from the same quality-assured foundation. |
Data processing zones
| Zone | Purpose |
|---|---|
| Landing | The entry point for data, where it is initially ingested. |
| Raw Archive | Stores raw data indefinitely, organised and tagged for audit purposes. |
| Trusted | Processes and publishes data in a standardised, easily consumable format. |
| Profile | Analyses data to discover new and missing data points without interrupting the loading process. |
| Published | Provides the selected table format for the agreed source delivery, facilitating SQL-based data access. |
| Integrated | An integrated core business concept data model using ensemble data modelling methodology. |
| Business | Use case-driven business data sets designed for specific scenarios, accommodating unique business and domain-specific definitions and rules. |
Next steps
- Platform guide — layer-by-layer deep dive into INGEST, DLS, DWA and QPI
- Data management capabilities — the full list of what the platform does, with links into the detail
- What lands in the target environment — the comments, keys, constraints, tags and masking generated into your database
- Your first pipeline — the end-to-end path from a source file to a scheduled data product
- Deploy — install and run the platform in your own environment
- Daily operations — monitoring and running the platform